An Ecommerce Hosting Downtime Example, Explained
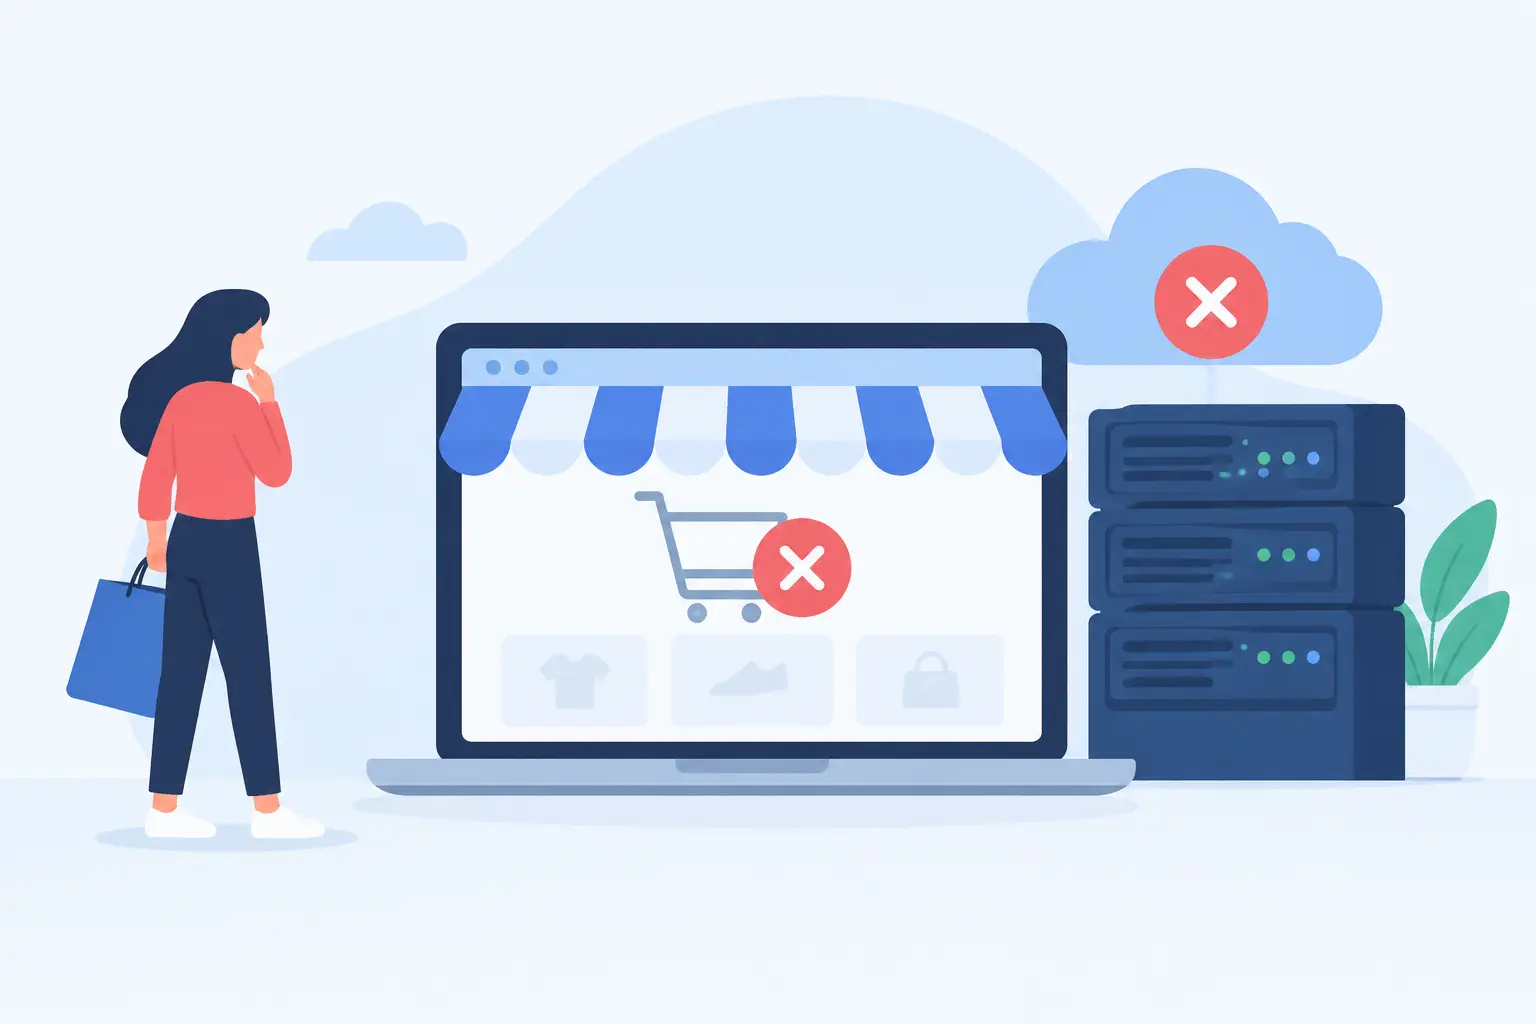
At 10:14 a.m. on a promotional Tuesday, an online retailer sends a high-volume email campaign. Within minutes, product pages begin timing out, carts fail to load, and paid traffic lands on error pages. This ecommerce hosting downtime example is not unusual because the original failure was small: a database volume reached capacity after backup files were written to the production disk.
The incident becomes expensive not because disk space is difficult to fix, but because the store has no early warning, no tested recovery procedure, and no engineer actively managing the stack. For an eCommerce business, downtime is rarely just a technical interruption. It is a direct break in the path from buyer intent to revenue.
Contents
The ecommerce hosting downtime example: what happened
Consider an illustrative scenario involving a growing WooCommerce store processing several hundred orders per day. The incident and timeline are hypothetical, but the failure mechanisms reflect real risks in production eCommerce environments. Its hosting environment runs the website, PHP workers, MySQL database, scheduled tasks, email integrations, and cached product catalog from a single cloud server. The configuration worked during ordinary traffic, but it had little room for a campaign spike or an unexpected maintenance failure.
A backup plugin was configured to create daily database archives locally before transferring them to remote storage. One transfer had been silently failing for several days. Each new archive remained on the server. Meanwhile, order data, logs, image uploads, and temporary files continued to grow.
At 10:14 a.m., the disk reached 100% capacity. MySQL could no longer write temporary tables or update order records. WooCommerce checkout requests began returning errors. A full-page cache allowed some visitors to browse category pages, but shoppers who added items to carts encountered inconsistent sessions and failed checkout attempts.
The merchant first learned about the problem through customer messages. Their marketing team paused the campaign 27 minutes later. A freelance developer was contacted, identified the full disk, deleted old archives, and restarted database services. The site appeared available again after 72 minutes.
That was not the end of the incident. The team still had to determine whether any orders had been paid for without being created correctly, reconcile inventory changes, review failed payment gateway callbacks, and respond to customers who assumed the store was unreliable. The visible outage lasted a little over an hour. The operational cleanup took most of the day.
Why a short outage causes disproportionate damage
A store does not need to be down for a full day to lose meaningful revenue. The most valuable visitors may arrive during a campaign, after a social mention, or in the narrow period between product launch and stock depletion. If checkout fails at that moment, many shoppers will not return later.
The immediate loss is straightforward: sessions that would have converted cannot convert. The less visible cost is harder to measure. Paid advertising continues spending unless someone pauses it. Customer service volume rises. Teams manually investigate orders and payment records. Returning customers may hesitate before purchasing again, particularly when the failure occurs during payment.
Search visibility can also be affected if repeated server errors prevent crawlers from accessing key pages. A brief isolated outage is unlikely to destroy rankings, but recurrent 5xx errors, slow responses, and unstable pages create a pattern that neither users nor search engines reward.
For stores running Magento, PrestaShop, OpenCart, osCommerce, or a heavily customized WooCommerce build, recovery can take longer than expected. Restarting a service may restore the storefront while background queues, inventory synchronization, payment callbacks, or cache invalidation remain unhealthy. Availability is not the same as full operational recovery.
The real failure was a lack of operational ownership
A full disk is a common infrastructure event, not an exotic disaster. It should be detected before it affects transactions. Monitoring should alert engineers at sensible capacity thresholds, with enough context to identify what is consuming storage. Backups should be stored off-server, verified, and governed by retention rules. Production systems should also have defined limits for logs, temporary files, and application-generated archives.
The weakness in this example was not simply that one plugin misbehaved. It was that no one owned the complete operating environment. The site owner assumed backups were working. The developer assumed hosting would flag a disk issue. The hosting provider supplied a server but did not actively manage the application, backup process, database health, or capacity planning.
That gap is where commodity hosting becomes risky for revenue-critical sites. A server can be technically online while the eCommerce application is unable to sell.
What should have caught the problem earlier
A properly managed environment uses overlapping controls rather than relying on one setting or one person. Disk monitoring is the first line of defense, but it is not enough by itself. Engineers also need to know whether a sudden storage increase comes from database growth, backups, logs, malware, cached files, or a failed deployment.
For an active store, the following controls work together:
- Capacity alerts should trigger well before storage exhaustion, with escalation if the condition is not resolved.
- Backups should run to independent storage, follow a documented backup retention policy, and be tested through actual restoration.
- Application and database monitoring should detect checkout errors, elevated response times, failed scheduled tasks, and service restarts.
- Log rotation and temporary-file cleanup should be configured for the real behavior of the site, not left to default settings.
- A staging process should prevent untested plugins, updates, and custom code from being introduced during revenue-critical periods.
These measures are not interchangeable. A backup does not prevent downtime. Monitoring does not repair a failing database. A high-availability design does not help if corrupt application code is deployed to every node. Reliable hosting comes from engineering the full chain of prevention, detection, response, and recovery.
Recovery time and data loss are different risks
When evaluating hosting resilience, two targets matter: recovery time objective, or RTO, and recovery point objective, or RPO. RTO answers how long the business can tolerate an outage. RPO answers how much recent data it can tolerate losing.
In the example above, the store might have an RTO of 30 minutes during business hours. Its actual recovery time was 72 minutes, before reconciliation work even began. If its latest valid database backup was from the prior night, the RPO could be nearly 24 hours. Restoring that backup would risk losing a day of orders, customer accounts, inventory updates, and content changes.
The correct targets depend on the business. A small catalog site with low daily sales may accept a longer RTO than a store processing orders across multiple time zones. A flash-sale retailer may need a much tighter response plan. What matters is making the decision deliberately and building the hosting architecture around it.
For some stores, a single well-managed server with rapid restore capability is the right balance of cost and reliability. For others, separate database resources, redundant application nodes, replicated storage, and managed failover are justified. More infrastructure can improve resilience, but it also adds complexity. If it is not monitored and maintained by people who understand the stack, it can create new failure points.
A practical response plan for eCommerce teams
When checkout errors appear, the first goal is to stop revenue loss from spreading. Pause paid campaigns if the storefront or checkout is unstable. Confirm the scope using an external check and a real customer journey: homepage, product page, cart, checkout, payment return, and order confirmation. A homepage loading successfully does not prove that the store can accept orders.
Next, preserve evidence before making broad changes. Record error messages, recent deployments, server resource levels, payment gateway events, and application logs. Restarting every service without diagnosis can obscure the root cause and make reconciliation harder.
Then assign clear ownership. One person should coordinate business communication and campaign controls, while a qualified engineer investigates the infrastructure and application layer. The engineering response should prioritize service restoration without risking data integrity. For example, deleting temporary files may be safe; blindly deleting database files is not.
After service returns, validate transactions. Compare payment gateway records with orders in the platform, check stock adjustments, inspect abandoned checkout sessions where possible, and contact affected customers with clear, accurate information. Finally, document the incident while the details are fresh. The useful question is not who made a mistake. It is which control should have prevented, detected, or shortened the failure.
Managed hosting changes the operating model
Performance-critical eCommerce hosting requires more than a control panel and a support ticket queue. It requires engineers who understand Linux, web servers, PHP behavior, database workloads, caching layers, security hardening, and the specific failure patterns of commerce platforms.
That is why managed cloud hosting should include proactive monitoring, hardened server configuration, managed backups, SSL lifecycle management, update planning, and a response process that treats checkout availability as a business priority. At Olvy, the objective is not simply to keep a server running. It is to operate an environment that is tuned, observed, and maintained for the website that generates your revenue.
The best time to test recovery is a quiet weekday, not ten minutes after a campaign launches. Ask who receives the first alert, how quickly they can act, where the last verified backup lives, and whether the team can prove that checkout still works after a restoration. Those answers turn uptime from a marketing claim into an operating discipline.
About Olvy ( www.olvy.net ) :
Olvy is a private and independent Limited Liability Company based in Bratislava, Slovakia, in the heart of Europe. We combined our invaluable 20+ years experience to develop innovative and reliable, lightning-fast and affordable Managed Cloud Hosting services for Everyone. From a small blog to a growing eCommerce – Olvy takes care of your website 24/7.
